Sorry, but no relevant information or results could be found for your search.
Zhipu AI's GLM-Image uses "semantic tokens" to teach AI the difference between a face and a font
Zhipu AI's new open image model combines an autoregressive language model with a diffusion decoder. The 16-billion-parameter model is designed to excel at rendering text in images and handling knowledge-heavy content.<br /> The article Zhipu AI's GLM-Image uses "semantic tokens" to teach AI the difference between a face and a font appeared first on The Decoder. [...]
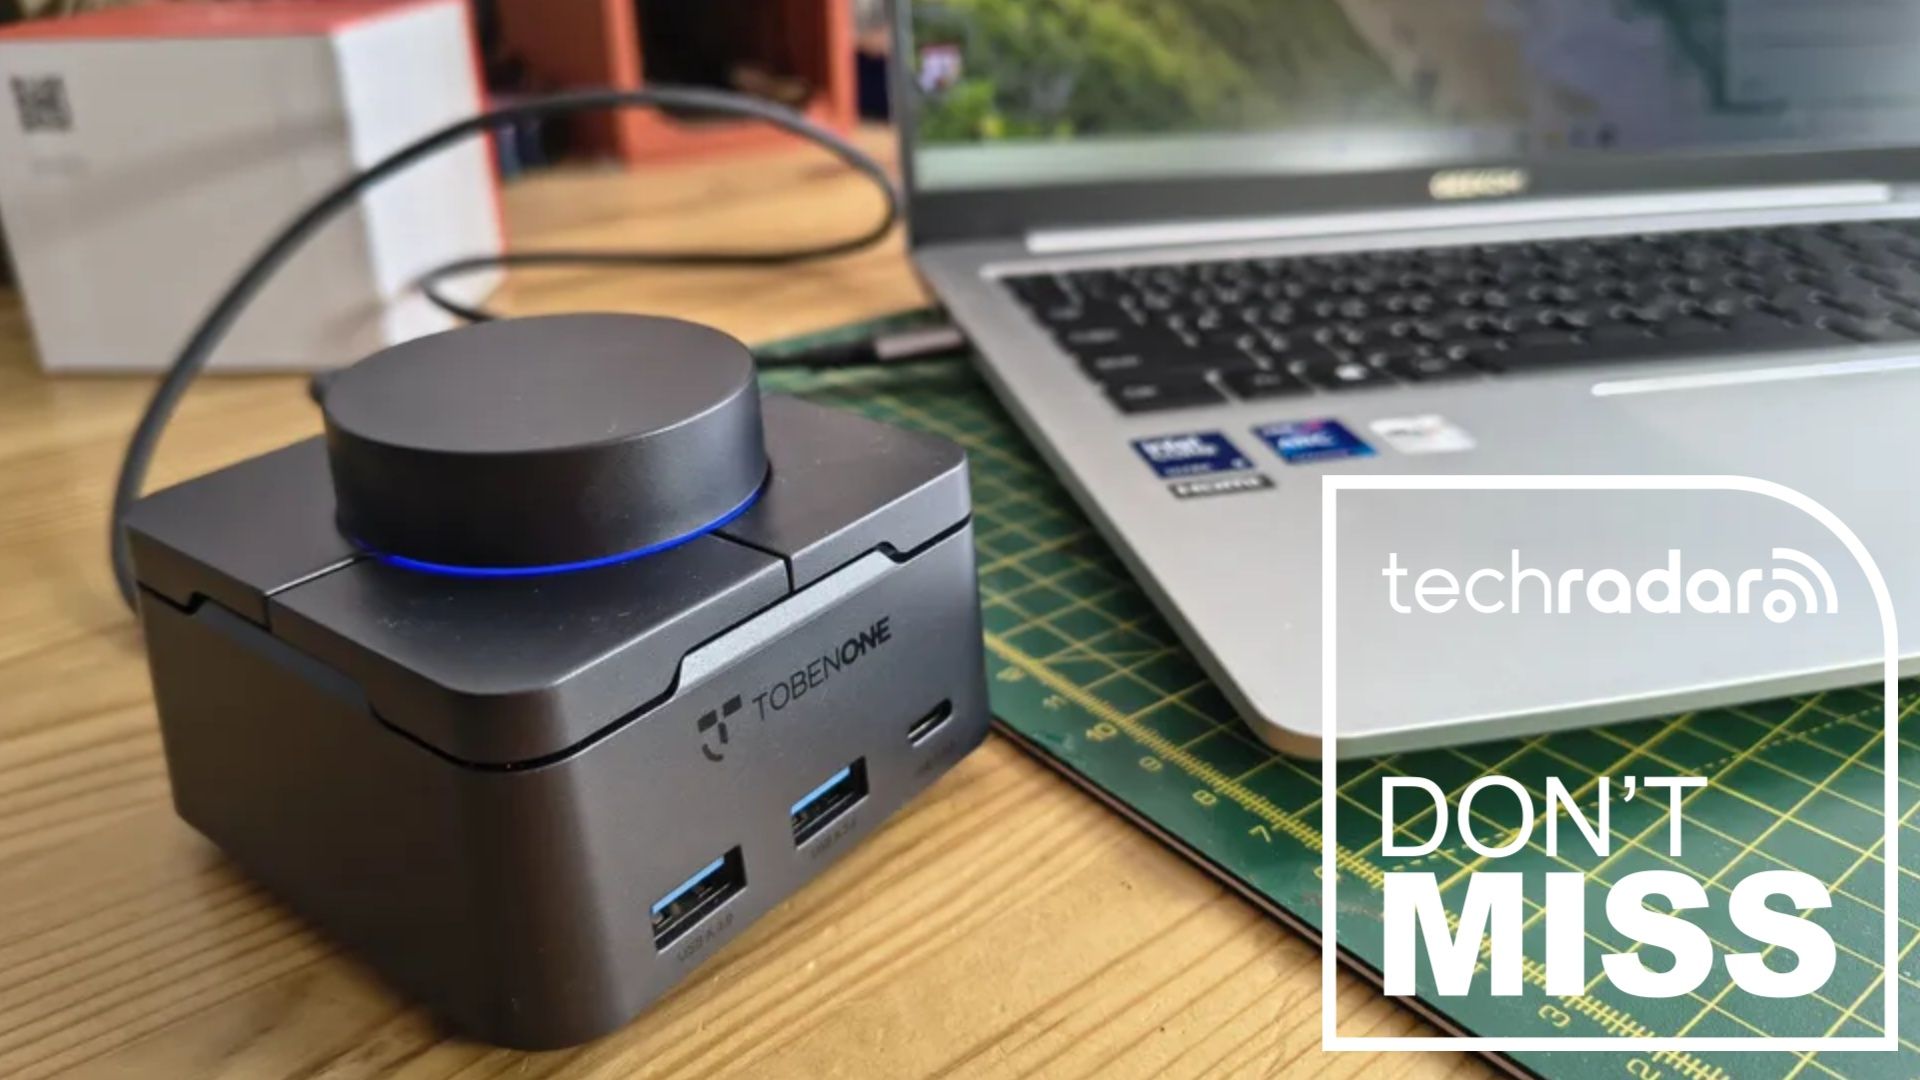
'A clever concept, and for those with a video or photo editing workflow, it's genuinely useful': The TobenONE 11-in-1 USB-C Docking Station is 36% off — now just $82.79
The TobenONE 11-in-1 USB-C docking station with dual 4K support and programmable controls is now 36% off at Amazon. [...]